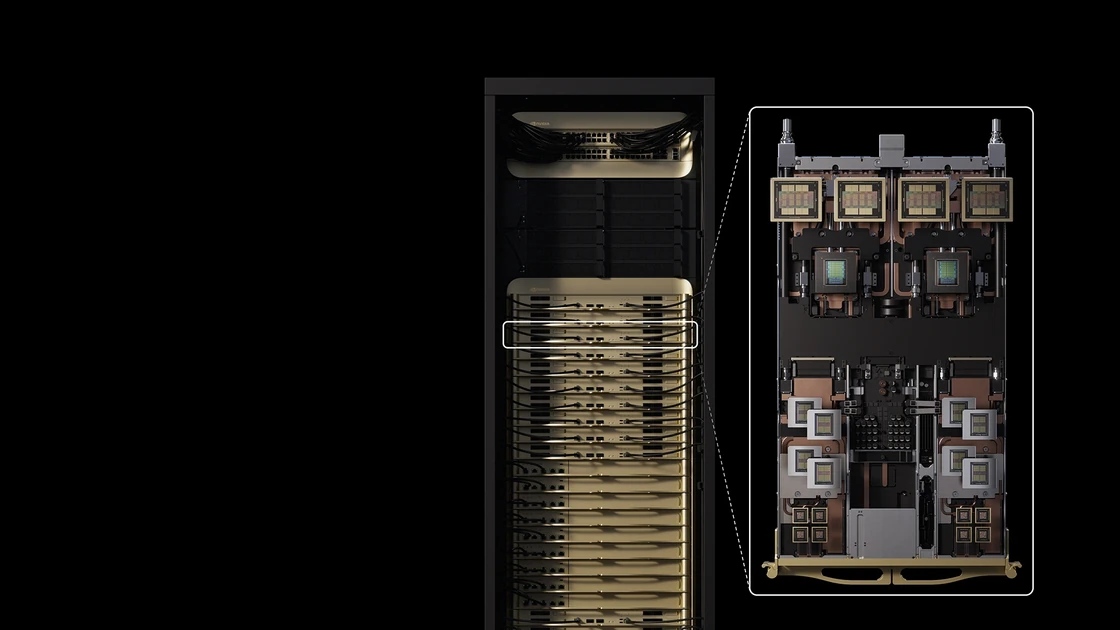
Nvidia says its Groq 3 LPX is four times faster than Cerebras, but the math is more complicated
Nvidia is moving its Groq 3 LPX inference chip into full production and reports 3,400 tokens per second on Gemma 4 31B, four times faster than Cerebras. The Register puts that in context. Nvidia needs at least 64 accelerators to get there, while Cerebras needs only one or two. How the architecture…
